LLM Preflight
Local, cross-provider preflight checks for LLM integration changes.
LLM Preflight
Last reviewed: 2026-09-30 · As of: v2.19.0


The pre-merge check for LLM changes. Catch model, prompt, schema, and provider-route regressions against your application's contract, then review latency, usage, and price evidence.
Try it in 60 seconds
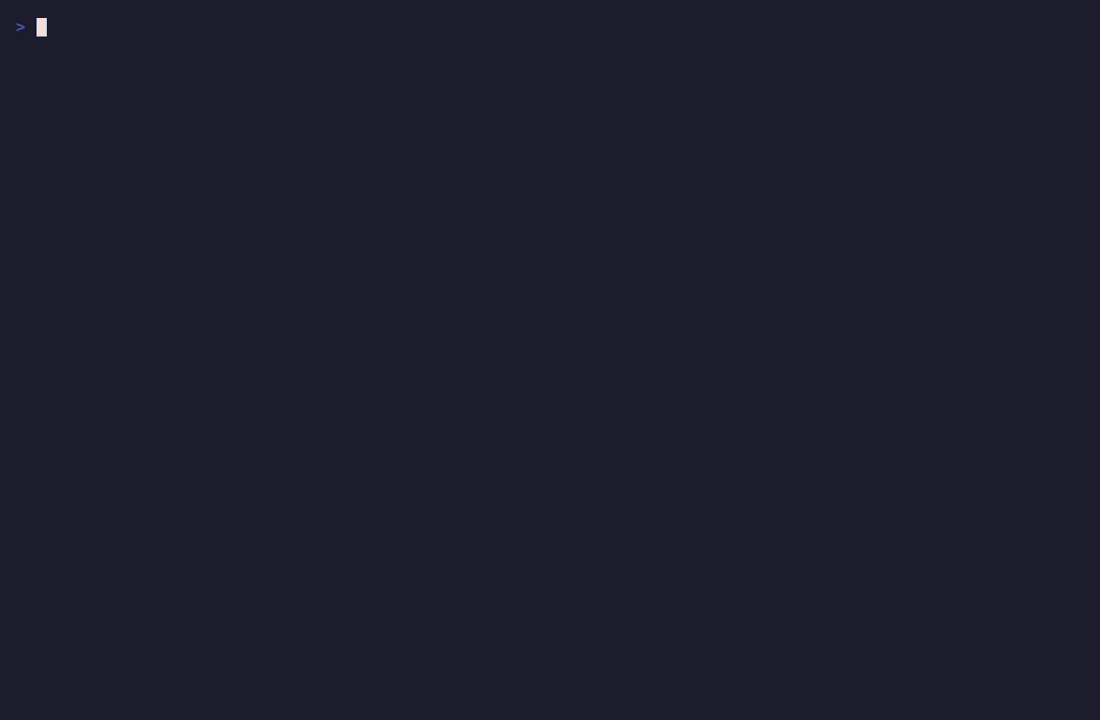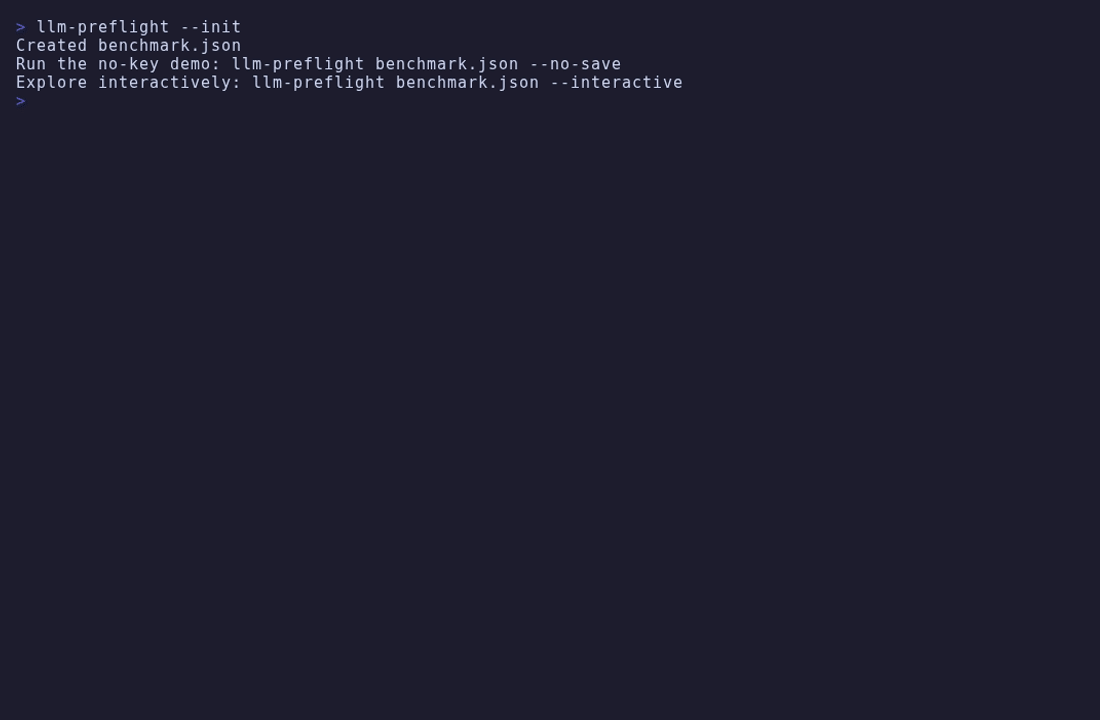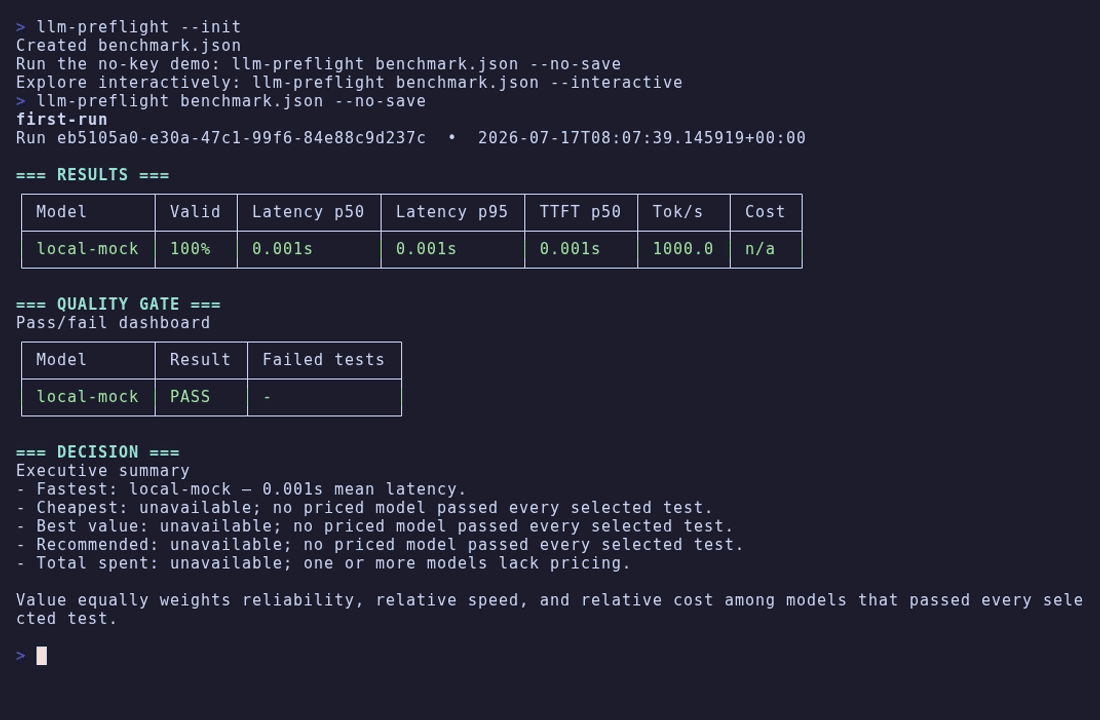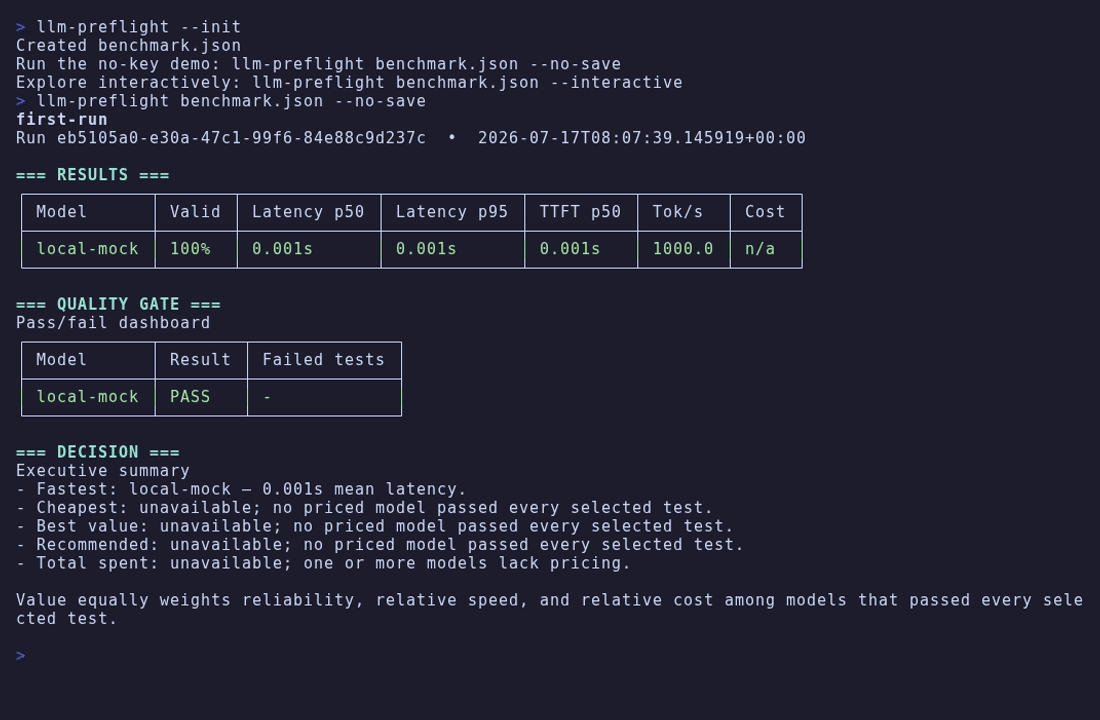
Create and run a deterministic local benchmark—no API key or network request:
python3 -m pip install llm-preflight
llm-preflight init
llm-preflight benchmark.json --no-save
From a source checkout:
python3 -m llm_preflight init
python3 -m llm_preflight benchmark.json --no-save
init never overwrites an existing config. It creates a mock benchmark so
you can see the report and exit behavior before making a paid request.
Its result is intentionally inconclusive (exit code 3): a local mock
validates configuration and output handling, but cannot approve a live model.
See a contract change fail
These saved results are synthetic fixtures. Render the same report you can attach to a pull request, without contacting a provider. From a checkout of this repository, run:
python3 -m llm_preflight report examples/reports/schema-baseline.json --format markdown
python3 -m llm_preflight report examples/reports/schema-break.json --format markdown
The first result passes. The second catches a response that no longer meets the declared output contract:
Decision: pass (benchmark_passed)
Contract validity: 100%

Decision: fail (contract_failure)
Contract validity: 67%
Contract-only failures: 1
The report gallery adds a cheaper candidate that fails the contract and a compatible baseline comparison with latency and cost regressions. Every number is labeled synthetic; none is a live model claim.
Choose your path
- Set up a real project. Adapt a representative contract, reuse an existing env file, and add a no-spend CI check with the project integration guide.
- Validate a change. Compare an approved model, prompt, schema, or provider route with a candidate using the model-change guide.
- Review a new model. Discover metadata, deliberately probe a route, then prepare a bounded candidate smoke with the model-catalogue guide.
- Inspect a measured example. See the dated support-routing model comparison to understand what a narrow contract run can and cannot establish.
- Automate an established contract. Add the no-spend GitHub Marketplace Action or use CI and JSON output.
- Configure a coding agent. Start the local MCP server from a trusted
repository with
llm-preflight-mcp --workspace "$PWD", then use the MCP server guide for your client configuration.
Safety boundary
flowchart LR
    A[Integration change] --> B[No-spend validation\ndoctor, pricing, dry run]
    B --> C{Human reviews\nevidence and cost bound}
    C -->|Explicit approval| D[Bounded paid smoke]
    C -->|No approval or missing evidence| E[Inconclusive: fix or stop]
    D --> F[Local evidence for\nproduction approval]
LLM Preflight is local evidence, not production approval. It is not a hosted evaluation platform, tracing system, RAG framework, or public leaderboard. Its results apply to your account, network, prompts, and validation rules.
[!WARNING] Live benchmarks make paid API requests. Start with the no-key demo, preview the plan before a live run, and keep limits and repetitions small.
CLI, CI, and MCP
Works as a CLI, GitHub Action, and local MCP server. Every path starts with no-spend validation and planning; a live provider run remains an explicit, bounded human-approved step. See the GitHub Action guide or the MCP server guide.
Version 2.18.1 preserves official provider adapter evidence when OpenRouter enriches catalogue entries and forwards system instructions in OpenAI Responses contract checks. The changelog records the release details.
Version 2.18.0 includes the evidence-integrity and output-validator corrections below. Native routes and release-reviewed official pricing snapshots are listed in current snapshots. That list is direct-provider price coverage, not a ranking or every discoverable ID.
Version 2.19.0 adds gpt-6.1-sol to the priced OpenAI candidate
set. Its official short-context rate is $2 input and $10 output per million
tokens, with $0.10 cached input; the snapshot table
also records its long-context rates. As with any candidate, check access and
run a bounded contract test before adopting it.
The same version adds native Z.ai glm-5.3 chat requests and official
pricing. Use provider: "zai" with ZAI_API_KEY; the
bounded comparison example reproduces
the eight support-routing cases. OpenRouter discovery uses z-ai/glm-5.3
and that route's live pricing.
Missing or malformed provider usage keeps cost unavailable, with known spend
shown as a subtotal. Strict pricing freshness applies to every source
description. Unsupported output-schema constraints fail before provider work.
Legacy results without request coverage show unverified cost evidence; unobserved
retry usage also prevents a complete total. The output subset enforces boolean
additionalProperties and inclusive finite numeric bounds, and records
validator semantics in provenance.
For earlier releases, see the changelog.
Purpose
Mission: help engineers catch LLM integration regressions before shipping a change.
Vision: every LLM-related pull request carries reproducible evidence of compatibility, latency, and cost.
Positioning: LLM Preflight is a local CLI and CI tool that checks an application's LLM contract and reports compatibility, latency, and estimated cost before a change ships.
It is built for small engineering teams maintaining AI features. Coding agents can run the same checks, while engineers own the decision. Read the north star and the AI implementation testing guide for the intended workflow and boundaries.
Common jobs
-
Switch a model or provider. Run the bounded migration check, then add the contract test your feature needs.
-
Check a prompt, schema, parser, or tool change. Define an explicit output contract before the smoke, then run
llm-preflight benchmark.json --contract-checkto prove local accepted/rejected fixtures and lint declared tool schemas. -
Plan an agent-made change. Run
llm-preflight benchmark.json --change-planbefore the ordinary no-spend checks. It identifies static model and contract signals in local Git changes, but never authorizes a paid run. -
Review a newly discovered model. Refresh metadata, then prepare—not run— a bounded candidate plan:
llm-preflight catalog refresh benchmarks/watch.json
llm-preflight catalog prepare benchmarks/watch.json \
  --against benchmarks/approved.json --output benchmarks/candidates.json
llm-preflight benchmarks/candidates.json --migration-check --dry-run
Only explicitly approved, fully evidenced models proceed to paid work; see the model catalogue guide.
-
Investigate a provider or price change. Run
--doctor,--pricing-check, and a dry-run; report a suspected regression through the redacted issue forms. -
Automate a known contract. Use the no-spend GitHub Action or the CI guide with a saved baseline and
--ci.
It measures deterministic test validity, end-to-end latency (p50/p95), time to first token, throughput when the stream is incremental and usage is available, token totals, and estimated cost. Result files retain request metadata and per-request observations for reproducibility.
"Deterministic" describes the validator, not the model: every response is checked against explicit structural rules — a regular expression, a JSON shape, an exact routing label — so the same response always produces the same verdict. The tool does not score semantic quality; that is your task-specific evaluation, and it stays out of scope on purpose.
What live evidence looks like
A completed preflight retains per-request observations and a machine-readable
decision: contract validity, latency (including TTFT where observable), token
usage, estimated cost, pricing evidence, and blocking warnings. The terminal
summary is a convenience; automation should consume the saved JSON decision.
Render saved schema-version-1 JSON as a self-contained offline HTML report with
llm-preflight report results/run.json --output report.html. The renderer
omits prompts, responses, local paths, and identifying run metadata; the
Marketplace Action adds a compact report to the GitHub Actions job summary.
That evidence applies to your account, network, prompts, and validator at one time—not a universal model ranking. For a complete interactive example, see interactive runs.
Model comparison
The comparison lists 26 exact API IDs: 26 measured. On 2026-09-28, we ran eight example support-routing and JSON cases twice each against 24 IDs. On 2026-09-30, the same cases were run against GPT-6.1 Sol and GLM-5.3 through OpenRouter / Relace: 16/16 and 14/16 valid outputs, respectively. GLM's result covers that routed endpoint. These observations apply to the dated example contract. The observed comparison has the scores, request settings, cost method, and failure analysis.
| Provider route | Model IDs | Evidence |
|---|---|---|
| OpenAI | gpt-6.1-sol | Measured 2026-09-30; 16/16 valid |
| OpenRouter / Relace | z-ai/glm-5.3 | Measured 2026-09-30; 14/16 valid |
| OpenAI | gpt-5.6-sol, gpt-5.6-terra, gpt-5.6-luna, gpt-6-sol, gpt-6-luna, gpt-6-astra | Measured 2026-09-28 |
| Anthropic | claude-opus-4-8, claude-opus-5-5, claude-fable-5-1, claude-sonnet-5, claude-sonnet-5-5, claude-haiku-4-5-20251001 | Measured 2026-09-28 |
| Gemini | gemini-3.5-flash, gemini-3.8-flash, gemini-3.1-flash-lite, gemini-3.1-pro-preview | Measured 2026-09-28 |
| xAI | grok-4.7, grok-4.6 | Measured 2026-09-28 |
| OpenRouter | qwen/qwen3.8-max-0902, qwen/qwen3.8-flash, deepseek/deepseek-v4-pro-0813, deepseek/deepseek-v4.1-flash, moonshotai/kimi-k3, moonshotai/kimi-k2.6 | Measured 2026-09-28 |
First live run
Python 3.10+ is required. There are no third-party runtime dependencies:
pip install llm-preflight installs this package and nothing else, and the
CLI runs on the Python standard library alone. Development tools (pytest,
ruff, mypy) are optional extras that never reach a production install.
cp benchmark.example.json benchmark.json
cp .env.example .env.production
# Edit benchmark.json and add only the provider keys you use.
python3 -m llm_preflight benchmark.json --dry-run
python3 -m llm_preflight benchmark.json
The CLI reads .env.production beside the config without overriding environment
variables already set by your shell. Use --no-env-file or --env-file PATH
when needed. Runs print a terminal report and, unless --no-save is used,
write JSON and Markdown results under results/.
Install the command globally in a virtual environment if preferred:
python3 -m pip install llm-preflight
llm-preflight --init
Run --doctor and --dry-run before the final command. They make no generation
requests; the final command is the paid work.
Change a model safely
This is the core workflow. Put your approved model and candidate model in one config, then run the small response-and-contract preflight:
llm-preflight benchmark.json --migration-check --dry-run
llm-preflight benchmark.json --migration-check
It sends three short representative cases to each selected model, once each. It answers: did the API work, did each response meet the basic contract, and how quickly did the provider start and finish responding? It is a cheap compatibility check, not a statistical performance conclusion.
When that passes, run the task-specific checks that match your application—for
example exact-routing-check or structured-output-check—before approving a
switch.
Use custom contract tests to express the outputs your
own feature must preserve.
Using a coding agent
Give an agent the same evidence you would use yourself: a reviewed config, an explicit output contract, and a dry run before paid work. Start with the recommended five-check suite:
# No generation request: inspect credentials, model selection, and paid-work plan.
llm-preflight benchmark.json --doctor --json
llm-preflight benchmark.json --tests agent-smoke --smoke --dry-run --json

# Paid run, only after reviewing the plan.
llm-preflight benchmark.json --tests agent-smoke --smoke --json --no-save
An agent should not infer model IDs, weaken a validator to turn a failure into a pass, or approve a model without an explicit instruction. The compact LLM and coding-agent guide covers commands, result JSON, exit codes, and automation guardrails. The AI implementation testing guide shows how to make this validation an agent's default testing step.
MCP for coding agents
Use the local stdio MCP server when an agent needs the preflight evidence without shell parsing or arbitrary command execution:
{
  "mcpServers": {
    "llm-preflight": {
      "command": "llm-preflight-mcp",
      "args": ["--workspace", "/absolute/path/to/repository"]
    }
  }
}
It exposes only four tools: validate a config, prepare a dry-run plan, run an explicitly confirmed preflight, and compare saved baselines. The first, second, and fourth tools never contact providers or load credentials. A live run still needs an explicit paid-run confirmation. See the MCP server guide for tool semantics, workspace boundaries, and the safe agent workflow.
Useful commands once you know your path
# Inspect configuration, credentials, and model selection without generation.
# --doctor provides pricing advisory; use --pricing-check as the fail-closed coverage gate.
llm-preflight benchmark.json --doctor
llm-preflight benchmark.json --pricing-check
llm-preflight benchmark.json --dry-run

# Run a reduced live benchmark.
llm-preflight benchmark.json --smoke

# Run a single ad hoc prompt.
llm-preflight --quick "Return only valid JSON with a status field." \
  --models openai:gpt-5.4-mini
For advanced discovery, interactive runs, CI, baselines, replay, and stop modes, see workflows. For models, environment files, custom prompts, and provider-specific options, see configuration.
What makes a comparison useful
- Keep prompts, system instructions, temperature, and output limits fixed.
- Validate outputs: a fast malformed response is a failed result.
- Run from the same host; network distance and provider load affect latency.
- Treat single-user latency and load testing as separate experiments.
- Prefer dated model IDs over moving aliases.
The CLI distinguishes API FAIL (transport, credentials, provider, or request
failure) from API OK / TEST FAIL (a response that fails your validator).
Recommendations only consider models that pass every selected test.
How it compares
Several good tools live near this space. Use them when their job is your job:
- promptfoo, deepeval — full evaluation suites: scored quality metrics, red-teaming, large ongoing test matrices in CI. Use them to grade prompt and model quality over time.
- Braintrust, LangSmith — hosted platforms: tracing, dashboards, team collaboration, production observability.
llm(Simon Willison) — a general multi-provider CLI for running prompts, not a comparison harness.
LLM Preflight does one narrower job: the local go/no-go check in the moment before an LLM integration change. Your prompt, candidate models, structural validation, latency, and cost — one command, one report, no hosted service, no telemetry, and no vendor between you and the verdict.
Documentation
Start at the documentation homepage, then choose the path that matches your work:
- Start safely: safe demo and model change.
- Validate a change: output contracts, model catalogue, and pricing and safety.
- Automate: CI and JSON output, coding agents, and MCP.
- Look up details: CLI reference, configuration, result JSON, and troubleshooting.
- Understand the product: north star, product decisions, and AI implementation testing.
- Contributing — development setup and the TDD workflow.
- Security — reporting vulnerabilities.
Contributing and license
Contributions are welcome; see CONTRIBUTING.md. Released under the MIT License.
Installation
Source-derived launch command. Check the maintainer’s required arguments and credentials before running:
uvx llm-preflightSet up in your AI client
Merge this template into ~/Library/Application Support/Claude/claude_desktop_config.json. Keep existing servers. Add any arguments, credentials, and permissions required by the maintainer; this template has not been install-tested.
{
  "mcpServers": {
    "io-github-feronovak-llm-preflight": {
      "command": "uvx",
      "args": [
        "llm-preflight"
      ]
    }
  }
}
Restart Claude Desktop completely for changes to take effect. Confirm the server appears connected in the client’s tool list, then try a read-only example from its documentation.
Claude Desktop setup referencePackage
llm-preflightpypiCompatible MCP Clients
LLM Preflight works with any MCP-compatible client. Copy the config snippet from the Configuration section above and add it to the file shown for your client, then restart the application.
- Claude Desktop
~/Library/Application Support/Claude/claude_desktop_config.jsonRestart Claude Desktop completely for changes to take effect. - Cursor
~/.cursor/mcp.jsonRestart Cursor for changes to take effect. - VS Code
.vscode/mcp.jsonReload VS Code window for changes to take effect. - Windsurf
~/.codeium/windsurf/mcp_config.jsonRestart Windsurf for changes to take effect. - Claude Code
.mcp.jsonSave at the project root, then start Claude Code in that project and review the MCP server approval prompt. Keep real credentials out of shared files.